 Taskuary
's whole behaviour is one loop: something arrives, it gets a verdict, the verdict decides who does the work, and whatever comes out waits for you. This page follows one message the whole way, then explains the machinery underneath it.
The work rail#
Every connection with a trigger or feed role lands on one rail beside the Assistant. An email from a vendor, a pull request, a Teams message, this morning's spend report and a failed nightly export are one list, sorted by what they need from you: Tasks, For later, Reports, Advisor and FYI. The filter at the top narrows it to one source or kind.
Tasks is every open task, an agent working on it or not - a ring spins round the icon of one an agent is working, and the row stays where it is when the agent asks or stops. An urgent row is shaded in its place, an important one wears a quieter mark, and Next reaches both in their places like any other row. A thread or a step gone quiet past that person's usual day is slipped, inside Tasks, with Chase, Let it go, They answered elsewhere and Remind me under it (see The Advisor).
A finished or closed item gets no row: the rail is what still wants something from you, never a history. Open a row and it goes on the table as its task - Came from, Agent and Close out - with what triage decided and why. See The work rail for what puts a row there and what takes it off.
The five roads a message can take#
Every message gets exactly one verdict, and there are only five places it can go.
| Road | What it means | What happens |
|---|---|---|
| fyi | nothing to do | filed; it stays readable and nothing is created |
| reply | a sentence settles it | a draft goes to the task for you to approve |
| coding | an agent at a keyboard | a CLI session starts in the checkout it picks |
| general | worth thinking about | a conversation opens on the task; no system is touched |
| task | yours to do | it lands on your list and nothing works it |
Three of those — coding, general, task — are kinds stored on the task, and the kind is
what routes the work. reply is a kind too. fyi creates nothing at all.
Triage has one more answer, watch: a thread you care about that somebody else will handle -
typically a colleague on the To line who has been answering asks like it. It takes the task
road with one difference: the task opens already under Watching, the same state
Watch it sets. Nothing works it and nothing is asked of you; it
is still walked after Tasks, comes back to Tasks when the thread moves, and Mark done lights
once a new message shows somebody else dealt with it. Its reason names who is expected to handle
it. Watch it, Stop watching and every other move work on it as on any task, and pressing
either one on a triaged item teaches triage for the next mail like it.
coding and general can start an agent by themselves, when Settings allow it and the sender is
someone Taskuary trusts; anything else waits for your Start. A task is yours by definition:
nothing works it.
What "general" means
It means the assistant's conversation: there is nothing to type at a system, but thinking,
reading or research an assistant can do and hand back — lay out the options, make sense of a
thread, work out what to ask. Work a person genuinely has to do in the world (sit a course, sign a
form, attend, decide), or something asked of you as yourself (your own invite, your own opinion),
is the task road instead.
What triage actually decides#
The verdict is the last thing that happens, not the first. Eleven checks run in a fixed order, and only two of them ask a model anything. A gate is deterministic: same input, same answer, no AI call, no cost. Knowing which is which is how you tell "triage got this wrong" from "a rule caught it before triage ever saw it".
| # | Step | Gate or AI | What it does |
|---|---|---|---|
| 1 | Dedupe | gate | A message whose id is already stored is dropped. Nothing below runs. |
| 2 | Feed connections | gate | A connection marked feed lands on the rail to read and stops — no verdict, no AI call, no task. |
| 3 | Policy rules | gate | Your rules, plus whether the sender is known. skip and ignore end it here. |
| 4 | Deferral | gate | Deferred triage lands the message as triaging so the rail shows it at once; the rest runs later. |
| 5 | Chat opener | gate | "hi", "you there?" — filed to wait for the ask it opens, so a greeting never becomes a task. |
| 6 | Threading | gate (scored) | Similarity against open tasks picks attach or create; then a thread that is not yours is refused. |
| 7 | Still the same ask? | AI | Chats only, and only when step 6 attached: does this line continue that task or start a new one? |
| 8 | Your standing ruling | gate | If you already ruled on this conversation it is filed, quoting your own words. Your rulings outrank the classifier. |
| 9 | An agent is waiting | gate | If a run is live on the attached task, no verdict is asked for — the message goes to the agent as its answer. |
| 10 | The verdict | gate, then AI | Tracker items, obvious noise and calendar mail settle with no call - an invite nobody has answered becomes yours to Accept, Decline or Propose a new time; an answer, an update or a cancellation is fyi. Everything else is one call reading TRIAGE.md, SOUL.md, JOB.md, LEARNED.md and your past verdicts. |
| 11 | Acting on it | gate | fyi files. A reply files instead of drafting when replies are off for that channel. watch becomes a task under Watching. Anything else becomes a task with its kind. |
Two rules hold wherever AI is involved. With no AI connector, a message is filed with "awaiting AI triage" rather than guessed at. A call that fails, or answers something unreadable, is filed too — never assumed to be work. Triage breaking is quiet and safe, not destructive.
So a message that never reached the classifier was stopped by steps 1–6 or 8–9, and the fix is a rule, a feed or a ruling. A message the classifier did judge and got wrong is corrected on the Triage tab.
Nothing sends itself#
Review is the outbound decision queue, and it is the only road out. A drafted reply sits there with the original request beside it; you edit the wording or the recipients, then Approve & send returns it through the channel the conversation started on. You can also ask for a redraft, reject it, or decide no reply is needed.
The same gate covers more than mail: a GitHub comment, an invoice, a bill posted to your finance system and a file written to a share are all proposals until you approve them. A connector card ships at a read-only authority, and raising it is a deliberate act.
One way to finish
A task ends with Mark done — on the task page, on the Assistant's card, or by saying "done" in the chat. Sending the reply marks it done too, unless an agent is still working on it or a new message arrived meanwhile. An agent that says it is finished closes its own task, and that result stays on your work rail until you have read it. See Tasks and agents.
Correcting it teaches it#
The roads on the Triage tab are not decoration. Correcting a verdict writes the reason into
TRIAGE.md, the document the classifier reads on the next message — so the correction applies to
the next message like this one, rather than becoming a rule about this one sender.
Every verdict is evidence. Editing a draft teaches voice; rejecting one teaches what should not
be drafted; Not our task teaches where your responsibility ends. What a verdict says about you
goes into LEARNED.md as one line under ## What you care about, in words - the kind of work and
why ("You handle vendor invoice disputes yourself - not agent work"), ending (about: …) when it
holds only for one sender or topic - so future triage, and the routing judge of a report, can judge
whether a new message is genuinely similar. A line is written only when it adds something: a verdict
that repeats what is already there writes nothing, and one that sharpens an older line replaces it.
Undo takes the line back out. What you tell the Assistant ("I don't care about the legacy export
any more") goes in as you said it. LEARNED.md is the one memory: there is no separate notes page or
table.
Repeated patterns become lessons in LEARNED.md, one section per subject: ## Your people,
## What you care about, ## How you work, ## Promises and ## What to bring up. Each reader
takes the sections that help it - triage, and a report's routing judge, read the whole of it on
every decision (your people for priority only), the Advisor your people, what you care about, how
you work and your promises, and the Assistant all of it. An agent's brief carries only the lines
about the people on its own task and reads the rest when it needs it (its owner_memory tool, or
taskuary --memory); on a stranger's task it gets none of it. Nothing is learned from a button press. How you write
is kept in STYLE.md under ## By recipient, for the drafter - with the instruction you typed into
Redraft, once you have typed the same one twice for the same person. Each machine-written line
carries its evidence:
- John drops greetings and signs off in one word. [s:4 | ev: rv12,rv15,rv31 | seen: 2026-08-19]
sis strength. A line starts at 2 under Watching, where nothing reads it, and is in use at 4 or more, supported by at least three episodes across two people or threads. Contradictions weaken it; stale hypotheses decay.evnames the verdicts that taught it, so you can go and read them.seenis the last date on which it held.
Delete a learned line and it stays gone: the next reflection cannot write it back unless its
evidence grows threefold. Reword one and your wording stays. Lines you write yourself carry no
machine tag and are never rewritten. An inferred rule that would hide work waits in Proposed rules
until you adopt it, and switching off a note it rested on takes it back there. Each reader takes its
section's lines closest to the message first, within a budget; a line that did not fit is recorded
as over budget, never cut in half. The opening screen says how many lines went into use this week
and are still in use.
SOUL.md always outranks LEARNED.md, and one setting switches the whole loop off.
Correcting it where you read it. About you → Memory reads LEARNED.md as plain sentences, one per
line, each with Keep, Wrong and Forget and a faint note of when it was learned and from what. The file itself
(open it from a search, or its What changed link) has three views: the text you edit, What changed and
Visualize. Visualize draws the five subjects, each saying who reads
it, with your people under the person each line is about and a link to that person's page where
the ledger keeps one; then Watching and Proposed. On a learned line, here and on its newest row in
What changed, three words correct it: Keep makes it yours, in its words, and nothing rewrites
it; Wrong takes it out for good - no reflection writes it back, whatever evidence comes;
Forget takes it out for now - it comes back only if its evidence grows threefold. A line you
wrote yourself takes Forget alone. None of this needs an AI; with none connected the page says
"Connect an AI to learn how you work", since nothing new is learned until one is.
Three brains, one voice#
Three always-on models do the thinking, and you talk to one voice. They are split by what each is allowed to read and to do, not by where they run.
| What it does | What it reads | When | Acts? | |
|---|---|---|---|---|
| Triage | Judges each arrival: task, goal, reply, watch, FYI or ignored. Attaches it to the thread's task, names the goal step a mail serves, opens a goal for the open-ended ask, names the profile, playbook and repository, assigns the worker | TRIAGE.md; the first 2,500 characters of SOUL.md and of JOB.md; LEARNED.md's promoted lines; routing memory; the playbook menu; the recent open tasks; the open goals and their steps |
every poll | makes rows; never sends |
| The assistant | The voice and the hands: walks the rail, runs set-up, connects things, moves things (assign, route, close, later) through a button or by asking the model for the verb | COUNSEL.md, SOUL.md and JOB.md whole and LEARNED.md's lines in use, on every page; the one item on the table and the page you asked about; STYLE.md, AGENT.md and the rest when you ask about them |
on a turn | moves things; never does the work, never proposes |
| The Advisor | The brain on the clock: the Advisor report, the morning brief and reflection say what is late, what was not followed up, what worked, which system is worth connecting | the head of SOUL.md and JOB.md, COUNSEL.md; your work as the hub sees it; the calendar; the knowledge base; the sources it watches; its own notes; LEARNED.md's promoted lines and the last month of the outcome ledger with the pages of the people it names. At reflection: LEARNED.md whole, hypotheses too, and the outcome ledger |
on its schedule and when the app opens; reflection at launch and after three corrections; and on the event - an agent stop or ask (or an agent cut off by a close, heard at the next launch), a reply, an attached mail, a PR, a close, a missed day, a report - one small prompt that leaves a line and a pill on that item | never; it leaves a line, an idea row or a proposal |
The workers (the coding agent, the general agent) are the fourth kind and not always on: they do
the work a task names, in a session you can watch. COUNSEL.md is the voice for the assistant and
the Advisor both. The split is a budget: the heavy reader works off the request path, on the
clock; the voice that answers on a turn reads the one item on the table, and never recomputes what
the Advisor computed.
The outcome ledger is the Advisor's newest input. Every other store is written at the moment
you click: the documents say what they say, LEARNED.md is what you do when you correct, and the
verdict and routing memories stop at the verdict. Nothing recorded what you did next, or what the
world did after Taskuary acted. The ledger does: one row per action the app took or proposed - a
reply sent, a task closed, an agent stopping and your next move in your own words, a pull request
merged, a promise made, a sender ignored - and a once-a-day sweep fills in what came of it from
facts already in the store: did more mail arrive on the thread, did the task reopen, did the
person deliver and when, did the ignored sender's mail become work anyway. No model runs in the
sweep. What the facts mean is reflection's: it reads the resolved rows as evidence (out ids,
beside the mem, rv and task ids above) and writes what you do into LEARNED.md with the same
grammar and the same decay - "a green PR from the coding agent is merged as it stands". A derived line never
acts on its own: the Advisor weighs it when it picks a button and words a proposal, and deleting it
from LEARNED.md is the whole undo. The whole of it - every input, the two clocks, the ledger's
row kinds and verdicts - is on The Advisor.
The documents that govern it#
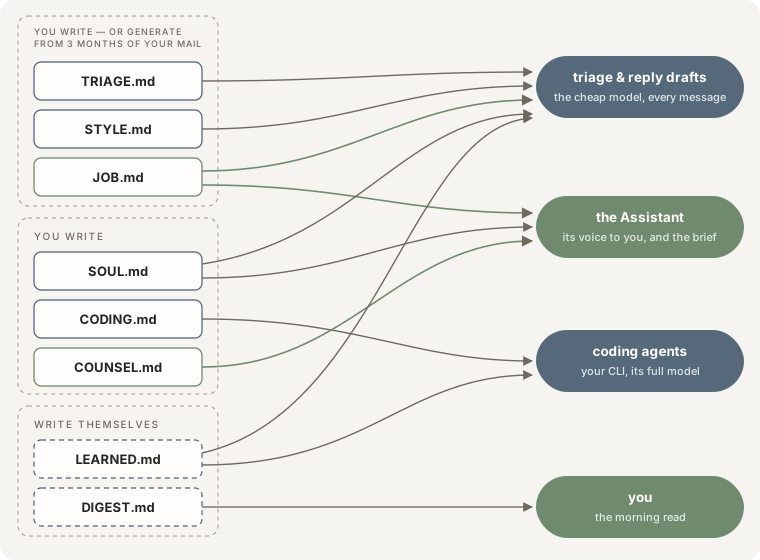
Taskuary's behaviour is plain Markdown under About you → Docs. These are not configuration files around the edges — they are what the models are actually told.
| Document | Purpose | Read by |
|---|---|---|
SOUL.md |
The constitution: rules, voice, escalation lines, repository map | triage, replies, the assistant |
JOB.md |
What your job is: mission, responsibilities, who you serve, the cadences, what to protect. It weighs importance, never intent | triage, the assistant, the morning brief |
TRIAGE.md |
What makes something a task, a reply, a watch or an FYI | triage |
STYLE.md |
Greeting, tone, length, phrasing | reply drafts |
COUNSEL.md |
How the assistant speaks, and how readily it takes a position | the assistant, the morning brief, replies |
CODING.md |
How coding agents work and close out | coding agents |
LEARNED.md |
What was learned from what you do, one section per subject; always below SOUL.md |
triage (What you care about), the Advisor, agents and the Assistant (the sections that help each) |
DIGEST.md |
The current morning brief | you |
| Playbooks | One page per kind of job: when it starts, which connections it uses, the steps, what an agent may do alone, what counts as done | triage's when line, and the agent working it |
Playbooks are the ones that grow. CODING.md is the playbook for code; every other kind of job —
a card charge to post as a bill, a new hire to set up — gets its own page the first time an agent
does it. On close, Taskuary asks whether that was a kind of job that will recur, and drafts the
playbook onto the task.
Generate from history on TRIAGE.md, STYLE.md and JOB.md bootstraps all of this from your
last three months of mail: it compares what arrived with what you actually answered, reads how you
write from your sent folder, and reads what your job is from both directions at once — who writes to
you, who you write to, what recurs and on what rhythm. Each writes its result into a marked block,
leaving anything you wrote outside that block alone.
Where the rest of the workspace fits#
- Board — queued, working, waiting and completed agent tasks, with a live terminal and the files changed so far on the working cards.
- Studio — agent capacity as a floor: one desk per slot, occupied when a task is running, a raised hand when a session needs you.
- Wall — every live terminal side by side, each with its own prompt box.
- Tasks — the durable task, its agent sessions and the reply, as three separate records.
- Review — the outbound queue.
- Reports — connected data on a schedule, routines and playbooks; see Reports and the Advisor.
- Hub — what agents have learned, by topic, so knowledge survives past one job.
- About you — your initials in the top right corner: who you are, the documents above, and what Taskuary has learned about you (Memory).
- Settings — everything else; see the Settings reference.